
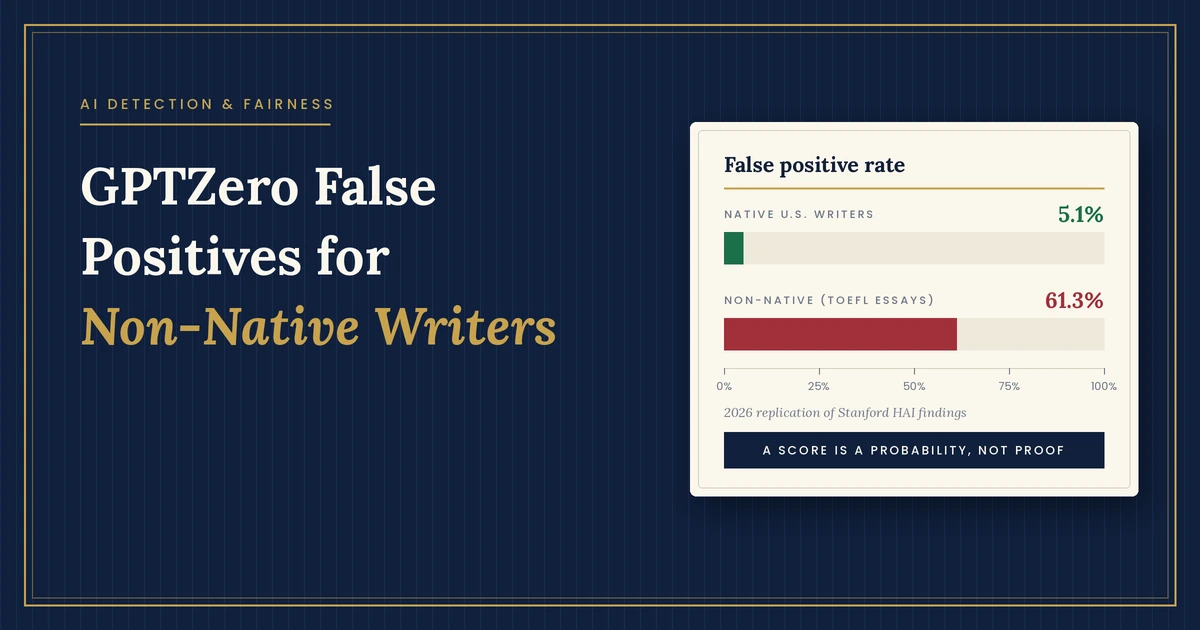
GPTZero False Positives for Non-Native Writers
A clear, grammatically correct essay should not become suspicious simply because its writer learned English as a second language. Yet research has found that AI-writing detectors can misclassify human-written essays by non-native English speakers at substantially higher rates than comparable writing by native English speakers.
This issue matters for international students, multilingual professionals, educators, and anyone whose writing is evaluated using AI detection software. A false positive can lead to unnecessary questioning, academic stress, or doubts about a writer’s integrity even when the work is entirely their own.
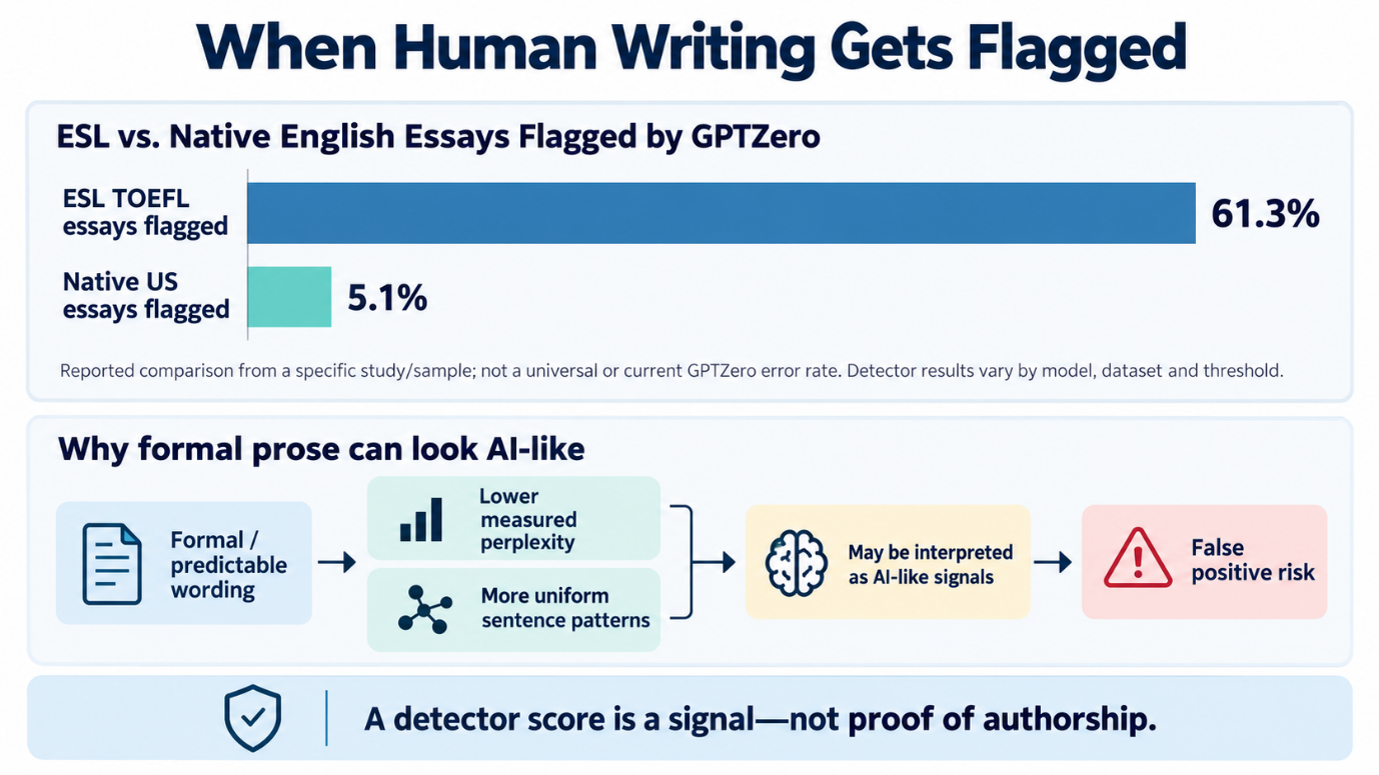
The central problem is that AI detectors analyze patterns in text, not the complete process that produced it. Formal vocabulary, predictable sentence structures, and conventional academic phrasing can overlap with patterns associated with AI-generated writing.
Research published in Patterns in 2023 brought this concern into focus. It found that seven AI-text detectors incorrectly classified a substantial share of human-written TOEFL essays as AI-generated. The findings do not establish a universal error rate for every detector today, but they demonstrate why a detector score should not be treated as conclusive proof of authorship.
Key takeaways
Research has documented disproportionate false positives for non-native English writing in particular datasets.
The widely cited 61.3% result was an average false-positive rate across seven detectors tested on a set of 91 TOEFL essays—not a current, GPTZero-specific rate.
Perplexity measures how predictable text is to a language model; burstiness is commonly used to describe variation in writing patterns, although detectors do not all calculate or use these signals in the same way.
Formal, conventional writing can be human-written even when its statistical patterns resemble AI output.
Detector results should be interpreted alongside drafts, revision history, research notes, and the writer’s explanation of their work.
Rewriting a flagged essay cannot guarantee a different detector result. The more reliable response is to document authorship and request a fair review.
What does GPTZero false positive mean?
A GPTZero false positive occurs when the tool classifies, or indicates a likelihood of, AI-generated writing even though a person wrote the text. More broadly, an AI-detector false positive is a human-authored text incorrectly identified as AI-generated.
These terms describe an error in classification; they do not establish why the error occurred in a particular case.
AI detectors can be useful as one source of information in a review process, but their results depend on the detector version, its classification threshold, the type of text being evaluated, and the dataset against which its performance is measured.
It is also important to distinguish three situations:
False positive: Human-written text is incorrectly flagged as AI-generated.
False negative: AI-generated text is incorrectly classified as human-written.
Uncertain result: The detector does not provide a confident classification or reports mixed signals.
All three matter when an institution is deciding whether to investigate a piece of writing. A tool that makes mistakes in either direction should not be treated as a definitive authorship test.
What research says about AI detectors and non-native English writers
One of the most widely cited studies on this issue is GPT Detectors Are Biased Against Non-native English Writers, published in the journal Patterns in 2023 by Weixin Liang and colleagues.
The researchers evaluated seven AI-text detectors using 91 TOEFL essays written by Chinese learners of English and 88 essays written by U.S. eighth-grade students. The study found that the detectors frequently misclassified the TOEFL essays as AI-generated, while performing much better on the U.S. student essays.
The average false-positive rate for the TOEFL essays was approximately 61.3%. The researchers also reported that 97.8% of the TOEFL essays were flagged by at least one of the seven detectors.
These results need careful interpretation. The study evaluated specific tools and samples available at the time; it did not establish that every detector, every version of GPTZero, or every non-native English writer will experience the same outcome. Its value lies in demonstrating a measurable fairness problem under the tested conditions.
ESL TOEFL essays vs. native U.S. essays
The comparison below illustrates the disparity reported for the study’s writing samples. The 61.3% figure is the average false-positive rate across seven detectors. The 5.1% comparison should be attributed to the specific dataset and analysis in which it was reported—not presented as a universal rate for native writers.
[Insert the accompanying infographic: “Human Essays Flagged by AI Detectors in One Study.”]
How to read the chart: The figures describe one research comparison, not the probability that any individual student will be falsely accused. Results may differ substantially across tools, versions, writing genres, and evaluation thresholds.
Source: Liang et al., GPT Detectors Are Biased Against Non-native English Writers, Patterns (2023).
https://doi.org/10.1016/j.patter.2023.100779
Why non-native English writing can be misclassified
The risk is not that non-native writers are inherently less credible. The concern is that some linguistic patterns associated with second-language writing can overlap with the statistical signals an AI detector uses.
1. Keep drafts and version history
Save earlier drafts and use the version-history features in tools such as Google Docs or Microsoft Word. These records may show how the argument developed and how the text changed over time.
2. Preserve research notes and source materials
Keep outlines, reading notes, source documents, calculations, and any relevant references. These materials can help demonstrate how the work was researched and assembled.
3. Ask for a human review
Request that the reviewer consider the detector result alongside the assignment requirements, available drafts, writing history, and the institution’s academic-integrity policy.
A detector score should not automatically replace a fair review of the evidence.
4. Explain your writing process
Be prepared to describe your argument, explain why you selected particular sources, and discuss how you revised the essay. A clear explanation of the work can provide useful context that a final-text detector cannot observe.
5. Be transparent about permitted writing assistance
If you used a grammar checker, translation tool, tutor, or editor, explain that assistance accurately and follow the rules that apply to your assignment. Policies differ, and legitimate language support should not automatically be treated as proof of misconduct.
What educators and institutions should do differently
Fair assessment requires more than selecting a detector and setting a threshold. Institutions should establish clear policies for how AI-detection results may be used, especially when the consequences of an incorrect decision are serious.
A responsible review process should:
Treat detector output as a prompt for further review, not a verdict.
Consider drafts, outlines, revision history, and source materials where available.
Give students a meaningful opportunity to explain their work.
Apply the same evidence standards consistently across students and writing backgrounds.
Distinguish prohibited AI-generated work from permitted proofreading, translation, or editing support according to the relevant policy.
Evaluate tools using representative samples and report both false positives and false negatives.
Avoid using a single detector score as the sole basis for a disciplinary decision.
Research into AI detection continues to evolve. For that reason, institutions should review claims about accuracy against independent evaluations and avoid assuming that a tool’s advertised performance will generalize to every student population or writing task.
Frequently asked questions
Why does GPTZero flag my writing when I did not use AI?
An AI detector may classify writing as AI-like because of patterns in vocabulary, sentence structure, or predictability. Formal academic prose and some second-language writing can share these patterns with AI-generated text. A flag is not proof that you used AI.
What does the 61.3% false-positive figure mean?
In a widely cited 2023 study, seven AI detectors had an average false-positive rate of approximately 61.3% on a sample of 91 human-written TOEFL essays. It describes that study’s results, not a guaranteed current GPTZero error rate.
Is GPTZero biased against non-native English writers?
Research has documented disproportionate false positives for non-native English writing in particular datasets and detector evaluations. The extent of the problem depends on the tools, samples, and conditions tested, so the findings should not be generalized to every current system or every writer.
Can I make my essay pass an AI detector?
No particular edit can guarantee a specific detector result. Rewriting solely to influence a score may change the text without resolving the underlying question of authorship. If you wrote the essay yourself, preserve your drafts and notes and request a review that considers the writing process.
Should teachers rely on AI-detection scores?
A score can be one signal that prompts a closer look, but it should not be treated as conclusive proof. Teachers should consider the available evidence, the assignment context, and the student’s opportunity to explain their work.
Does low perplexity prove that an essay was written by AI?
No. Low perplexity means that a passage is relatively predictable to a reference language model. Human writing can be predictable, particularly when it follows conventional academic or professional styles. Perplexity alone cannot establish authorship.
Conclusion: A detector score is not proof of authorship
GPTZero false positives raise an important question about how AI-writing detection should be used in education and professional settings. Research has shown that human-written TOEFL essays can be misclassified at high rates by AI detectors, demonstrating that writing style and language background can affect classification outcomes.
Perplexity, burstiness, and other textual patterns may help explain why some passages are classified as AI-like. But these patterns are not the same as direct evidence of who wrote a passage.
The practical response is not to assume that every detector is useless, nor to accept every result as accurate. It is to recognize the limits of automated classification and combine it with context, transparent policies, and human judgment.
Human-written work deserves to be evaluated on evidence, not on a probability score alone.
Sources and further reading
Liang, W. et al. (2023). “GPT Detectors Are Biased Against Non-native English Writers.” Patterns.
https://doi.org/10.1016/j.patter.2023.100779Stanford Institute for Human-Centered AI. “AI Detectors Biased Against Non-native English Writers.”
https://hai.stanford.edu/news/ai-detectors-biased-against-non-native-english-writers
These sources provide research context for the findings discussed above. The results should be interpreted within their study conditions rather than as universal performance estimates for all current AI detectors.